Deep Learning Projects For Students
October 23, 2026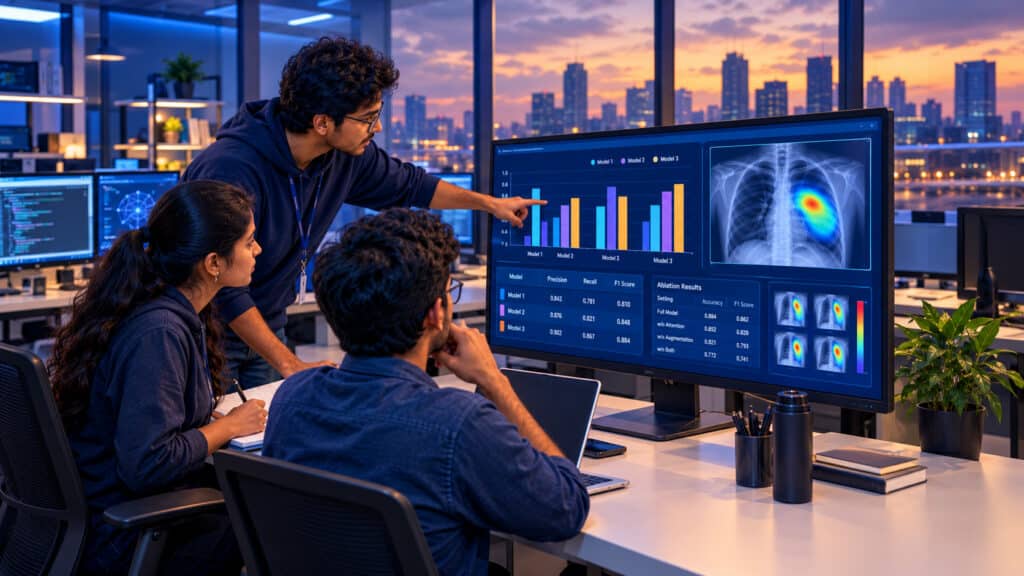
Introduction
A fine-tuned ResNet with 98% accuracy no longer impresses final year examiners on its own. They have seen dozens. What they want to know is whether it beats a fair baseline, which design choices matter, and whether it still works on data from somewhere else. Those questions define strong deep learning final year projects.
Many teams struggle because they treat deep learning as a coding exercise. However, the highest marks go to teams that treat it as a small research study.
This guide shows you how. You will learn what makes a deep learning project final-year worthy, how to choose a research-grade topic, 25 deep learning final year project ideas with gaps and metrics, a review-by-review plan and a complete architecture comparison build. Along the way, the mentors at Elysiumpro share what they see in the highest-scoring AI capstones.
What Are Deep Learning Final Year Projects?
Deep learning final year projects are capstone projects in which students design, train and rigorously evaluate neural network models for a meaningful problem over one or two semesters. They combine engineering, experimentation and research writing. In short, they show that you can produce trustworthy AI results, not just working code.
- Research gap:A clear limitation in a recent paper that your work addresses
- Baselines:At least one standard model trained under the same conditions.
- Ablation study:Experiments that show which components actually help.
- External validation: Testing on data from a different source.
- Explainability and reporting: Grad-CAM or attention maps, confidence intervals and honest limitations.
What Makes a Deep Learning Project Final-Year Worthy?
A Deep learning project becomes final-year worthy when it moves beyond training one model to answering a research question with controlled experiments. The table below contrasts a typical mini project with deep learning capstone projects.
| Component | Typical mini project | Final-year worthy project |
|---|---|---|
| Problem | Reuse a Kaggle task | Address a gap from a recent paper |
| Models | One pre-trained network | Two or three architectures plus a baseline |
| Experiments | One training run | Ablations on augmentation, loss or architecture |
| Testing | Dataset's own test split | Held-out test set plus external dataset |
| Reporting | Accuracy only | Task-appropriate metrics with confidence intervals |
| Explainability | None | Grad-CAM, attention maps or SHAP |
| Efficiency | Not measured | Parameters, inference time and model size |
| Deliverables | Notebook and short report | Prototype, report, viva and often a paper |
How Do You Choose a Research-Grade Topic?
Choose a research-grade topic by finding a recent paper in a domain you care about, identifying a specific weakness, confirming that two datasets and enough GPU time are available, and defining the metric that will prove your improvement.
- Pick a domain.Healthcare, agriculture, Indian languages, traffic and accessibility offer strong impact.
- Read recent papers.Search IEEE Xplore or arXiv for work from the last two to three years.
- Name the gap.Common gaps include poor generalisation, high compute cost, bias across groups or lack of explanations.
- Secure two datasets. One for training and testing, another for external validation.
- Budget compute. Estimate GPU hours per run and multiply by the number of planned experiments.
- Fix the metrics. Choose metrics that match the task, such as AUC, Dice, mAP, WER or macro-F1.
- Plan the ablations. Decide which components you will switch off to prove they help.
What Are the Best Deep Learning Final Year Projects for 2026?
The best deep learning final year projects for 2026 tackle a real gap with public data and measurable outcomes. Here are 25 advanced deep learning projects across five areas, each with a gap, a dataset and a key metric.
Medical imaging projects
| Project | Research gap | Dataset | Key metric |
|---|---|---|---|
| Pneumonia detection with external validation | Single-hospital models fail elsewhere | Pediatric chest X-ray (Kaggle) plus an external set | AUC, sensitivity |
| Explainable diabetic retinopathy grading | Clinicians distrust black boxes | APTOS 2019 | Quadratic kappa |
| Fair skin lesion classification across skin tones | Bias against darker skin | HAM10000 plus Fitzpatrick17k | Balanced accuracy per group |
| Lightweight brain tumour segmentation | High compute cost | BraTS | Dice score, parameters |
| Semi-supervised retinal vessel segmentation | Scarce expert labels | DRIVE | Dice with limited labels |
Vision and video projects
| Project | Research gap | Dataset | Key metric |
|---|---|---|---|
| Helmet and triple-riding detection in Indian traffic | Dense, mixed traffic scenes | Indian Driving Dataset or own data | mAP, FPS |
| Field-robust crop disease detection | Lab-to-field accuracy drop | PlantVillage plus PlantDoc | Field-image accuracy |
| Indian Sign Language recognition from video | Continuous signing | INCLUDE (ISL) dataset | Accuracy |
| CCTV violence detection | High false alarms | Public violence video datasets | F1, false alarms per hour |
| Generalisable deepfake detection | Unseen generation methods | FaceForensics++ (on request) | Cross-dataset AUC |
NLP and Indian-language projects
| Project | Research gap | Dataset | Key metric |
|---|---|---|---|
| Code-mixed Hinglish sentiment analysis | Mixed-language text | SemEval-2020 code-mixed data | Macro-F1 |
| Indian legal judgment summarisation | Very long documents | Public Indian legal corpora | ROUGE |
| Regional-language fake news detection | Low-resource languages | Public Indic fake news datasets | Macro-F1 |
| Hallucination detection for RAG chatbots | Factual errors in answers | Own question-answer set | Precision, recall |
| Accent-robust speech recognition | Errors on Indian accents | AI4Bharat or Common Voice | Word error rate |
Audio and multimodal projects
| Project | Research gap | Dataset | Key metric |
|---|---|---|---|
| Cross-corpus speech emotion recognition | Dataset-specific overfitting | RAVDESS plus CREMA-D | Unweighted average recall |
| Hindi image captioning | Few non-English captioning models | Flickr8k with Hindi captions | BLEU, CIDEr |
| Visual question answering for agriculture | Domain-specific questions | Own crop image QA set | Answer accuracy |
| Noise-robust audio-visual speech recognition | Poor accuracy in noise | Public lip-reading datasets | Word error rate |
| Indian bird species recognition from audio | Regional species coverage | xeno-canto recordings | Macro-F1 |
Efficient and trustworthy deep learning projects
| Project | Research gap | Dataset | Key metric |
|---|---|---|---|
| Pruning and quantisation for edge deployment | Size versus accuracy trade-off | CIFAR-10 or own data | Accuracy, MB, latency |
| Adversarial robustness of image classifiers | Vulnerability to small perturbations | CIFAR-10 | Robust accuracy |
| Federated learning for medical images | Privacy limits on data sharing | Public medical image sets | Accuracy across rounds |
| Comparing explanation methods | Unclear faithfulness of explanations | Any public vision dataset | Deletion and insertion AUC |
| Continual learning without forgetting | Catastrophic forgetting | Split CIFAR | Average accuracy across tasks |
How Do You Plan Deep Learning Final Year Projects Review by Review?
Plan deep learning final year projects by tying each college review to a concrete experimental milestone: data and baseline first, then main models, then ablations and external validation, and finally explainability and writing. The plan below fits a typical 20-week final year.
| Review | Typical weeks | Deep learning deliverables |
|---|---|---|
| Zeroth review | 1–3 | Title, base paper, research gap, datasets confirmed, compute budget |
| Review 1 | 5–7 | Literature survey, data pipeline, baseline model trained and evaluated |
| Review 2 | 10–13 | Two or three architectures trained under identical settings, first comparison table |
| Review 3 | 16–18 | Ablation studies, external validation, confidence intervals, explainability maps |
| Final viva | 19–20 | Report, demo app, recorded backup video, optional paper draft |
Above all, freeze your data splits at Review 1. Changing them later makes every comparison unreliable.
How Do You Compare Architectures Step by Step?
Compare architectures by fixing the data splits, training each model with the same budget and augmentation, evaluating on an internal test set and an external dataset, running ablations and reporting metrics with confidence intervals. The worked example below follows this method.
Worked example: pneumonia detection with external validation
A team of three final year CSE students studies whether chest X-ray models trained at one hospital generalise elsewhere. This is a research exercise, not a clinical tool. They follow six steps.
- Fix the data. Use a public pediatric chest X-ray dataset for training and testing, and a different public chest X-ray source as the external set.
- Train a baseline. Fine-tune ResNet50 with standard augmentation.
- Train challengers. Fine-tune EfficientNet-B0 and a small vision transformer with identical splits, epochs and image size.
- Run ablations. Remove augmentation, then remove class weighting, and record the effect.
- Validate externally Evaluate every model on the external set without retraining.such as flips and colour changes.
- Explain and report. Generate Grad-CAM maps and compute bootstrapped confidence intervals.
The team uses this short script to report metrics with a 95% confidence interval:
from sklearn.metrics import classification_report, f1_score
y_true = np.load("test_labels.npy")
y_pred = np.load("test_preds.npy")
print(classification_report(y_true, y_pred, digits=3))
rng = np.random.default_rng(42)
scores = []
for _ in range(1000):
idx = rng.integers(0, len(y_true), len(y_true))
scores.append(f1_score(y_true[idx], y_pred[idx], average="macro"))
low, high = np.percentile(scores, [2.5, 97.5])
print(f"Macro-F1 95% CI: {low:.3f} to {high:.3f}")
Illustrative results
| Model or ablation | Internal AUC | External AUC | Parameters |
|---|---|---|---|
| ResNet50 (baseline) | 0.96 | 0.81 | ~25 M |
| EfficientNet-B0 | 0.97 | 0.84 | ~5 M |
| Small vision transformer | 0.96 | 0.79 | ~22 M |
| EfficientNet-B0 without augmentation | 0.95 | 0.74 | ~5 M |
| EfficientNet-B0 without class weighting | 0.96 | 0.82 | ~5 M |
These figures are illustrative. However, they show the kind of findings examiners reward: every model drops on external data, augmentation matters most for generalisation and the smallest model performs best. Grad-CAM maps that sometimes highlight text markers instead of lungs add a powerful discussion of shortcut learning.
Which Viva Questions Should You Prepare For?
Prepare for questions about your research gap, experimental fairness, generalisation and limitations. Every team member should answer confidently. Expect questions like these:
- What gap in the base paper does your project address?
- Why did you choose these architectures?
- How did you ensure a fair comparison between models?
- What did your ablation study reveal?
- Why does performance drop on the external dataset?
- How do you know the model looks at the right features?
- How large is your model, and could it run on a phone?
- What are the ethical risks and limitations of your system?
What Mistakes Should You Avoid?
Most lost marks in deep learning final year projects come from unfair comparisons, missing validation and unclear contribution rather than poor code. Avoid these mistakes:
- Comparing models under different settings. Keep splits, epochs and augmentation identical.
- No baseline.Without one, your improvement cannot be judged.
- Testing only on one dataset. Add external validation wherever possible.
- Data leakage.Keep images from the same patient, video or speaker in a single split.
- Ignoring compute limits. Plan runs carefully and save checkpoints.
- Overclaiming. Medical and safety projects are research prototypes, not deployable products.
- No explainability. Grad-CAM or attention maps strengthen both the report and the viva.
Where Can You Get Expert Guidance?
You can get guidance from your faculty guide, research groups, open-source communities and specialist mentors. Resources such as Papers with Code, PyTorch tutorials and the Hugging Face course help you reproduce baselines quickly.
For a complete capstone, structured mentoring helps you define the gap, design fair experiments and write a strong report. For example, Elysiumpro mentors deep learning academic projects, covering title selection, experiment design, implementation training and documentation while students build and train the models themselves. Whichever route you choose, make sure you can defend every experimental choice.
Conclusion
Deep learning final year projects earn top marks when they behave like small research studies. Start from a clear gap, compare architectures fairly, run ablations and test on external data. Then explain your models, report confidence intervals and discuss limitations honestly.
In short, rigorous experiments beat bigger models. If you want guidance turning one of these 25 ideas into a high-scoring, publishable capstone, connect with the AI mentors at Elysiumpro and start your research today.